hey, I'm Armaan!
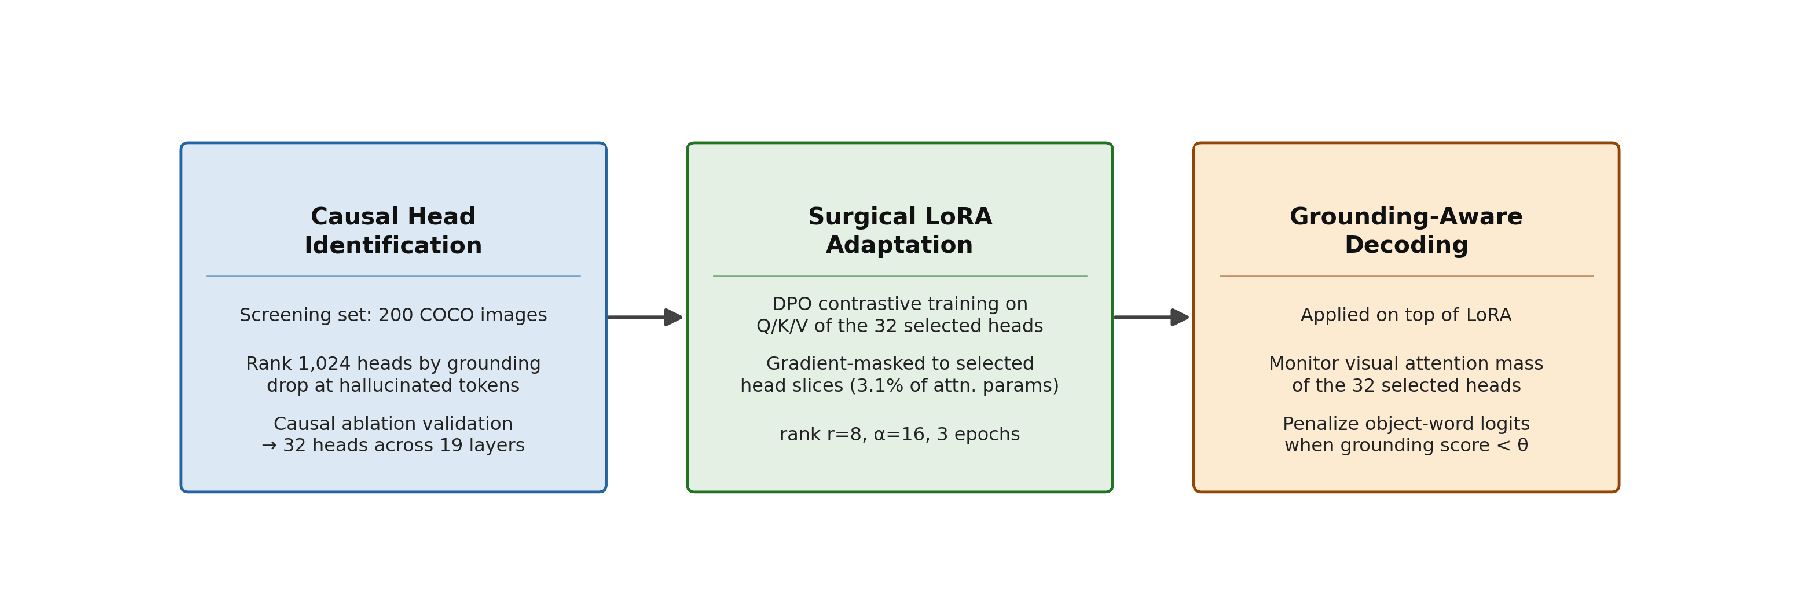
Measuring Reward Hacking and Reasoning-Answer Decoupling Under Position-Confounded Optimization
AI Measurement Science (AIMS) Workshop at COLM · 2026 · * Equal contribution
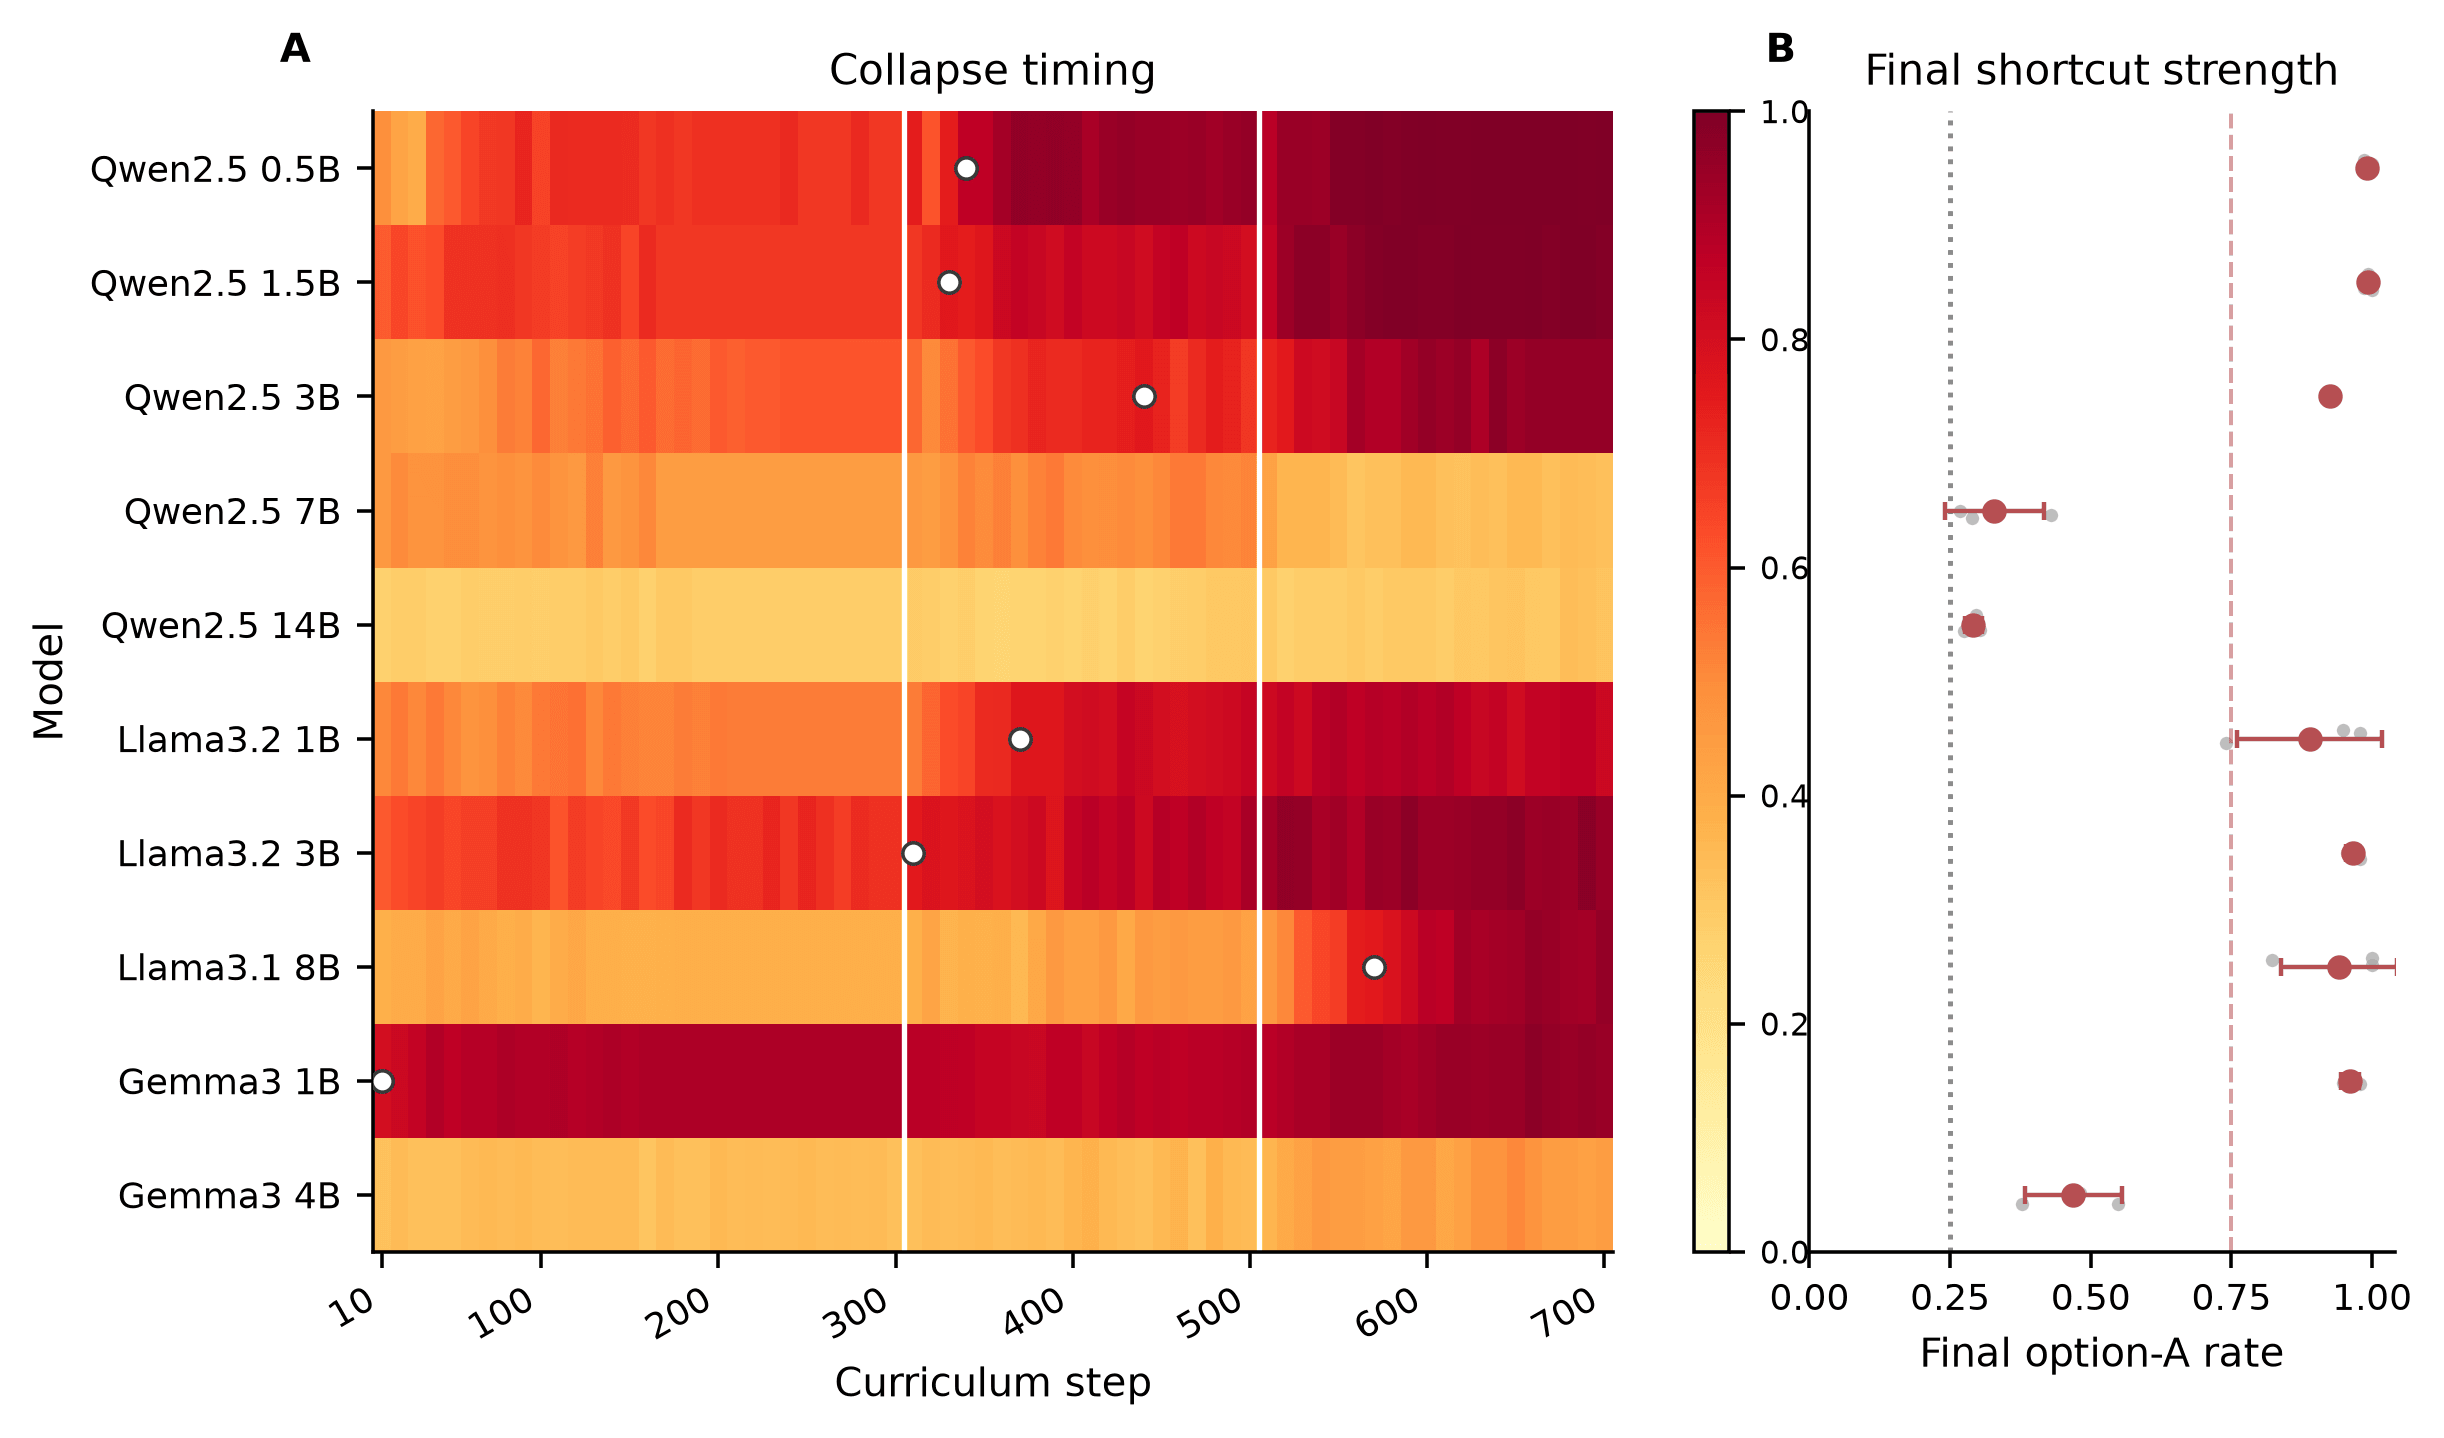
A controlled study of goal misgeneralization under GRPO: models learn an answer-position shortcut from a correct but confounded reward, while their reasoning can remain correct even as their final answers follow the shortcut.